

Ensemble Methods: Bagging, Random Forests, and Stacking Without the Jargon 2026?
Single models fail in unpredictable manners. Ensemble Methods combines multiple models to be more accurate and stable like asking a committee instead of one expert. Bagging, forests, and stacking are your go‑to patterns.
Connect With Us: WhatsApp
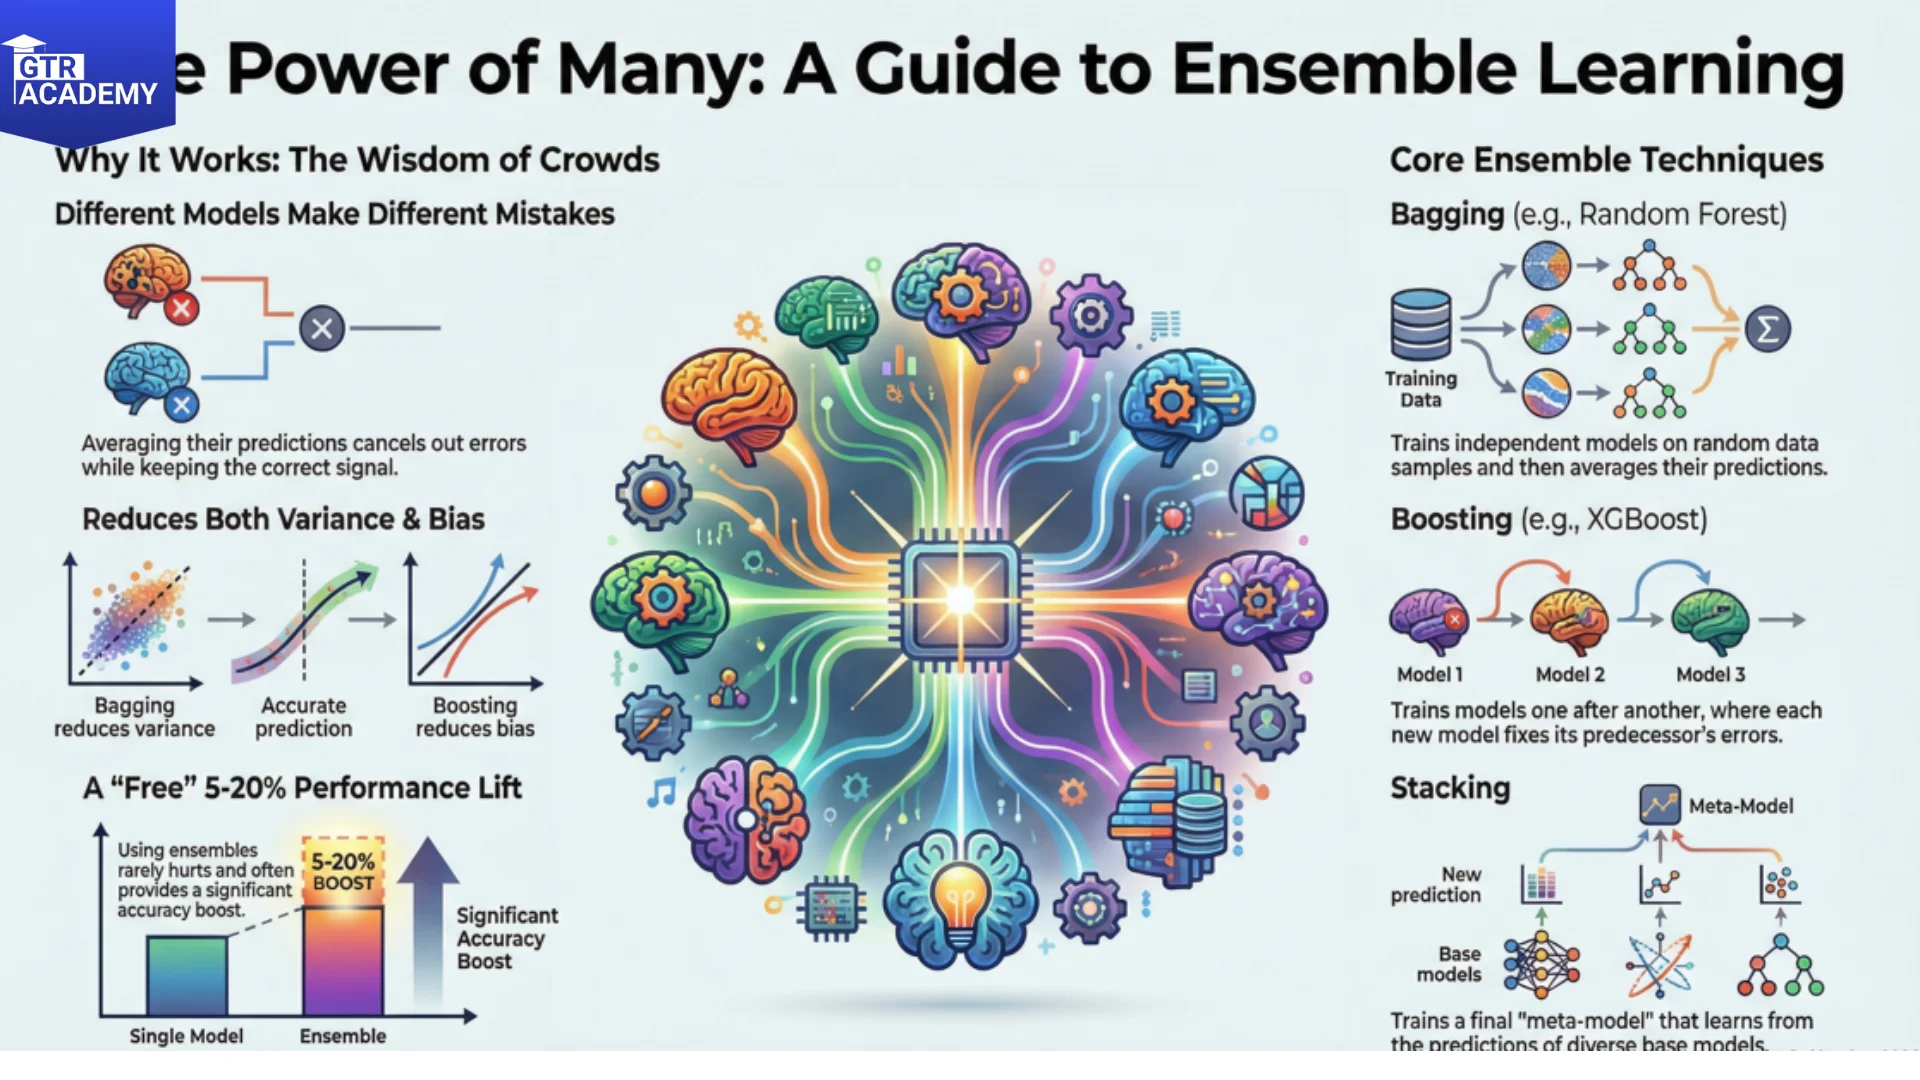
Why ensemble works
Wisdom of crowds:
- Different models make different mistakes.
- Average their predictions → cancel errors, keep signal.
- Reduces variance (bagging) and bias (boosting).
No free lunch: Ensembles rarely hurt; often give 5–20% lift “for free.”
BAGGING: Reduce variance with bootstrapping
Bagging (Bootstrap Aggregating):
- Draw bootstrap samples (with replacement) from training data.
- Train independent model on each (usually trees).
- Average predictions (regression) or majority vote (classification).
Random Forest: Bagging + random feature subsets per split:
- Prevents trees from becoming too similar.
- Built‑in feature importance.
- Handles missing values, non‑linearities.
BOOSTING recap (connects to Day 3)
Sequential trees fixing prior errors (Boost, Light, Cat Boost).
Ensemble strategy: Blend random forest (low variance) + gradient boosting (low bias).
STACKING: Meta‑learning across models
Stacking:
- Train diverse base models (RF, GBM, SVM, neural net).
- Generate out‑of‑fold predictions on validation set.
- Train meta‑model (simple linear/logistic) on those predictions.
- Predict: base models → meta‑model.
Pro tip: Use scikit‑learn Stacking Classifier/Regressor 3 lines of code.
Example: churn prediction showdown
Mini benchmark table:
| Model | CV AUC | Speed | Interpretability |
| Logistic | 0.82 | Fast | High |
| Random Forest | 0.87 | Medium | Medium |
| Boost | 0.89 | Medium | Medium |
| Stacked Ensemble | 0.91 | Slow | Low |
Ensemble Methods wins but consider deployment cost.
Connect With Us: WhatsApp
Try this: Take a churn dataset. Fit RF + XGB → simple average or stacking. Watch 2–5% lift with zero tuning.